 Botmonster Tech
Opus 5.5 is the Claude comeback Reddit was waiting for

Opus 5.5 is the Claude comeback Reddit was waiting for. It dropped the caveats and jargon that made Opus 5 hard to read, and the most-upvoted hands-on comment calls its writing an order of magnitude better. Codex and Astra users say they are switching back, though Fable 5.1 still wins some coding tests and cynics expect a nerf.
Key Takeaways
- Reddit’s biggest praise for Opus 5.5 is that it finally talks like a person.
- Some people who left Claude for Codex and Astra say they’re coming back.
- Heavy users say hours of work barely dent their usage limits.
- Fable 5.1 still wins some side-by-side coding tests.
- Plenty of redditors expect an unannounced nerf within two weeks.
What is Reddit saying about Opus 5.5?
The mood across the Claude and OpenAI communities on Reddit is relief. People who tested the model name the same things in the same order: the voice fix first, then the usage limits, then speed. Benchmarks come a distant fourth.
The busiest Opus 5.5 thread isn’t even in a Claude forum. A meme thread in r/OpenAI , Reddit’s main OpenAI community, outscored Anthropic’s own launch post in the r/ClaudeAI forum . Its title claims Opus 5.5 is 80% cheaper than GPT-6 Astra. That loosely echoes Anthropic’s announcement , which says Opus 5.5 at default effort beats Astra at max effort on two benchmarks, for about a fifth of the cost per task.
The top reaction there came from a user who keeps leaving:
Literally every time I cancel my claude subscription they drop some crazy shit
The top reply told them to keep cancelling.
The official facts in brief
Anthropic says Opus 5.5 performs at the level of Fable 5.1 on most work. It also cuts the price and speeds up output. The model ships as claude-opus-5-5 on the Claude API, AWS, Google Cloud and Microsoft Foundry.
| Price per million tokens | Opus 5 | Opus 5.5 |
|---|---|---|
| Input | $5 | $4 |
| Output | $25 | $20 |
| Cache reads | $0.50 | $0.20 |
| Fast mode (up to 2.5x speed) | n/a | $8 in, $40 out |
On typical workloads at default settings, Anthropic puts the saving at 40% against Opus 5, because the new model also uses fewer tokens per task. Output comes more than 30% faster. The cache-read cut does the most for agents, since Anthropic says cache reads make up the majority of agentic and coding costs, and prompt caching is what keeps a long session cheap.
One of the launch thread’s biggest comments cheered a new Haiku , yet no new Haiku shipped. The joke answers one line in the announcement: Sonnet 5.5 and Haiku 5.5 will follow in the coming weeks.
Opus 5.5 finally talks like a person
Reddit’s Opus 5 verdict was a genius that will not shut up . Opus 5.5 is being praised for fixing exactly that. This comment from r/ClaudeCode, Reddit’s hub for Anthropic’s coding tool, is the most-upvoted tested verdict in the whole launch:
The way Opus 5.5 communicates is genuinely an order of magnitude improvement over Opus 5. Seeing a lot less “caveats” and “one thing worth knowing”.
Over in r/ClaudeAI, a relief post titled Claude is BACK! reached 1,575 votes. Its author, a few hours into the new model, said Claude felt like a collaborator again instead of a jumpy, jargon-heavy liability.
Opus 5’s pet phrases became the running joke
Opus 5 had a vocabulary everyone learned to hate: “load-bearing,” “footgun,” “blast radius.” Before launch, r/singularity was pleading for those words to go. After launch, r/ClaudeCode was checking whether they were gone. Until now, the usual workaround was to rein in Opus 5 with an output style and a hook .
Testers report that the Opus 5 verbosity and hallucinations have disappeared . In the r/codex forum, where OpenAI’s coding tool lives, one user says the new Opus finally writes plain English .
A philosopher’s read on the new voice
The best non-coding review came from a philosophy graduate who interviews every new model . The post found Opus 5.5 smoother and quicker to agree than earlier Opus models, closer to recent GPT models in how it opens a reply. Even so, it still pushes back on the user’s assumptions. The verdict: a model you can test ideas against without flattery or constant hedging.
One reply called the review contradictory, since a model can’t both agree faster and challenge you more.
Codex and Astra users say they are coming back to Claude
The top reply in the “Claude is BACK!” thread came from someone who had left:
I had actually let my 20x sub not renew, and moved to Astra, because I was sick of Opus 5 “pant’s and suspenders” talk and “just two more things”.
About a week later, that user is back on Claude and happy with it. Even an OpenAI loyalist in r/OpenAI called Opus 5.5 shockingly fast and the most productive model they had used.
In r/codex, a Codex subscriber on the $200-a-month plan since 2025 argued that Codex is now in a bad spot (437 votes). The trigger was a single 20-hour Astra session that burned the whole Codex limit. Then Opus 5.5 arrived faster and with looser limits, so the post says OpenAI is behind on both.
Claude Code also won back another user who had moved to Astra full time.
The OpenAI side pushes back
OpenAI’s defenders are fewer. The highest-voted rebuttal in r/codex rates Astra above Fable 5.1 and denies it is slow , while conceding that Opus 5.5 is in a good spot. In r/OpenAI, a software engineer argued that Sol 6 covers their work for a small fraction of Opus 5.5’s cost.
Another r/codex regular says Claude’s limits are still worse than OpenAI’s, and that Opus wins on taste and prose rather than on getting work done. Readers weighing the OpenAI side can compare Reddit’s take on GPT-5.6 Sol .
How far do Opus 5.5 usage limits stretch?
Anthropic raised five-hour limits on Pro, Max, Team and seat-based Enterprise plans. It also gave every subscriber one rate-limit reset they can bank and use whenever they choose. That second perk drew loud cheers in the launch thread. For heavy users weighing a plan, the $200 Max tier’s real cost is the other half of the question.
The hands-on claims are stronger than the official ones. The author of a 1,428-vote r/ClaudeCode thread had worked for a full day on the top plan:
Been working non stop since release and has barely made a dent on my 20X Max usage.
The most concrete number comes from another r/ClaudeCode user . They ran five Opus 5.5 subagents at max effort to fix five bugs that Fable had missed. The job took 14 minutes and used under 15% of a five-hour limit on the 5x Max plan.
The Max effort tier and the “benchmaxxing” charge
Opus 5.5 adds a Max effort setting, and the Claude app warns it burns several times more usage. A r/ClaudeAI thread (412 votes) asked whether Anthropic benchmarks at Max while subscribers run cheaper tiers. The top reply takes the air out of the scary number:
the “6x or more” is just a consequence of making “medium” default, rather than “high”. So you’re looking at 6x more than medium, rather than 1.5x (or whatever it was) more than high.
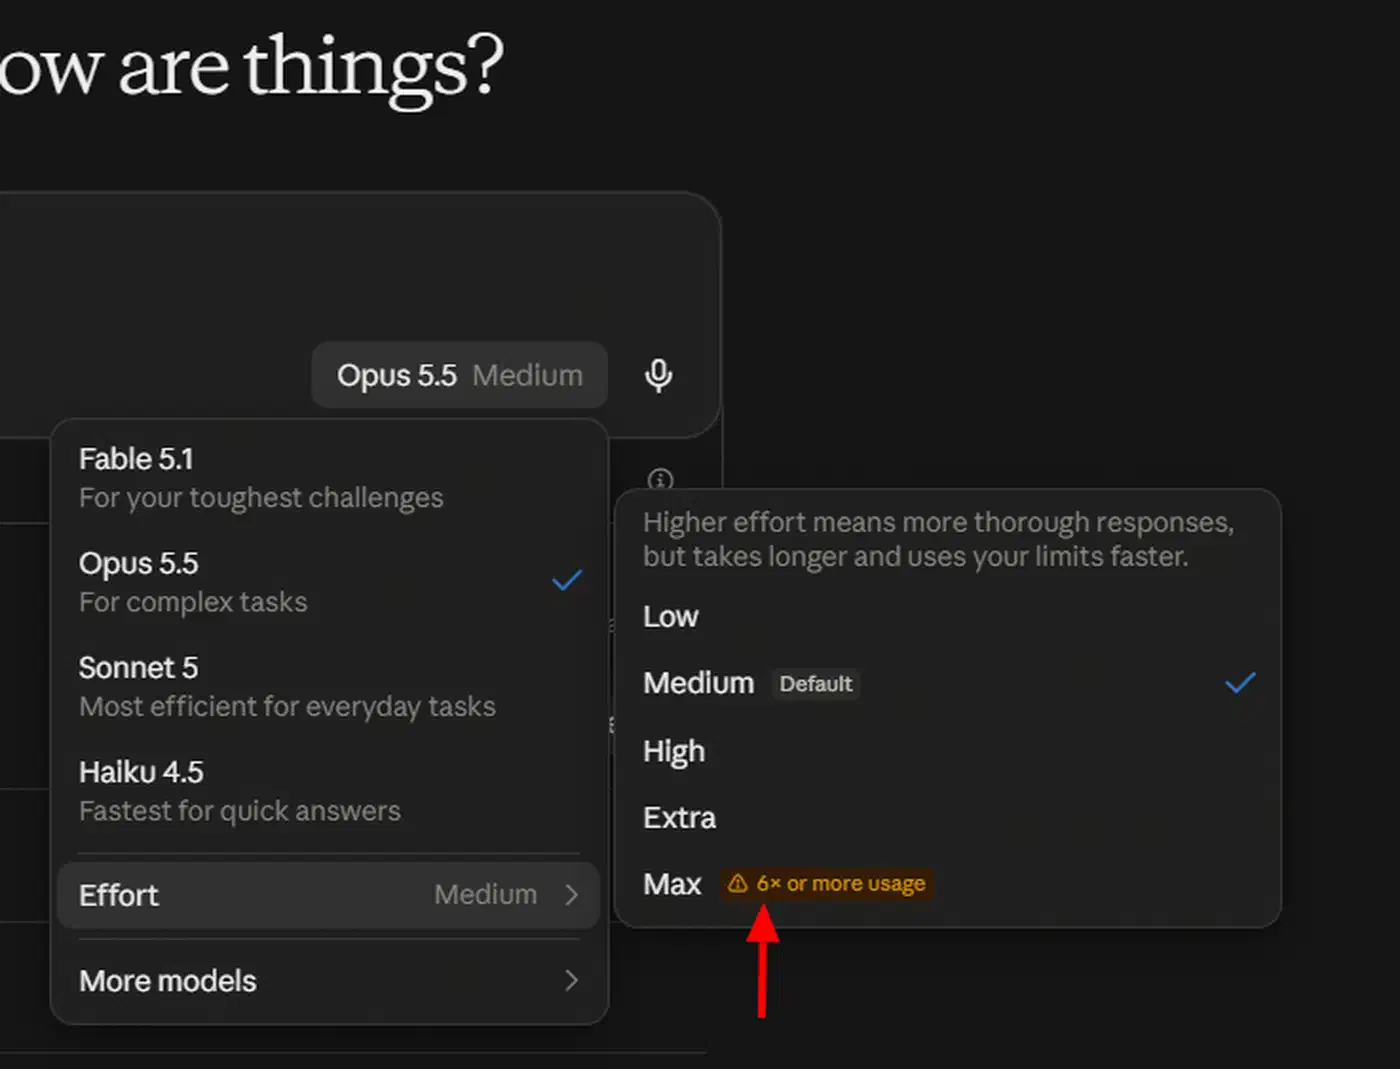
Anthropic’s docs confirm it: Default effort on Opus 5.5 is medium, where Opus 5 defaulted to high . At the same effort level, Opus 5.5 also thinks more per turn than Opus 5, most of all at xhigh and max. Anthropic publishes no fixed multiplier for Max, and redditors report seeing 4x, 5.5x and 6x.
The announcement’s benchmark footnote does say all Opus 5.5 results use max effort unless noted. However, Anthropic also publishes default-effort numbers. At medium, Opus 5.5 scores 54.6% on FrontierCode, above Astra’s best of 53.3%. It scores 52.5% on CursorBench against Fable 5.1’s 51.8% at max.
In practice, experienced users call high or xhigh the sweet spot and say Max tends to overthink. On a light coding task, one tester saw no drop in token use at all. And a well-liked joke in r/codex held that Claude and generous limits should never go together.
Is Opus 5.5 better than Fable 5.1?
The Fable-level claim sent r/ClaudeCode straight to the obvious question. The top comment in the thread asking what Fable is still for (1,199 votes) asked it plainly:
has anyone tested opus 5.5 enough to know wether it’s a fable replacement? opus 5 was touted as one and it was clearly worse.
The answer from people who ran both is “for some work.” The next reply argued that Fable is a much bigger model and still cracks harder problems. On the Opus side, a former Fable-only user now calls Opus 5.5 good enough for a daily driver. Another tester in the same thread says it is cleaning up mess that Fable couldn’t fix.
By contrast, the best same-task report in the whole set goes against Opus:
I tried Opus 5.5 xhigh and Fable 5.1 high on the same request to implement a feature in my app. Opus 5.5 made some very questionable architectural decisions and agreed that they were not great.
Anthropic’s numbers, and why Reddit discounts them
Anthropic’s table puts Opus 5.5 ahead on almost everything. All figures are at max effort, except Opus 5.5’s Terminal-Bench score, which is at xhigh.
| Benchmark | Opus 5.5 | Fable 5.1 | Opus 5 | GPT-6 Astra |
|---|---|---|---|---|
| Terminal-Bench 4.0 | 66.4% | 55.8% | 52.3% | 57.9% |
| FrontierCode v1.1 | 54.4% | 50.3% | 48.0% | 53.3% |
| GDPval-AA v2.1 (Elo) | 1846 | 1735 | 1708 | 1542 |
| Humanity’s Last Exam | 67.7% | 65.6% | 63.6% | 57.2% |
| OSWorld 2.0 | 81.8% | 80.7% | 74.0% | not reported |
Astra leads on two tests: AutomationBench (41.4% against 40.0%) and Terminal-Bench-Science (64.6% against 58.7%). Anthropic also ran Opus 5.5 with its production safeguards on. When they stepped in, cybersecurity tasks fell back to Opus 4.8.
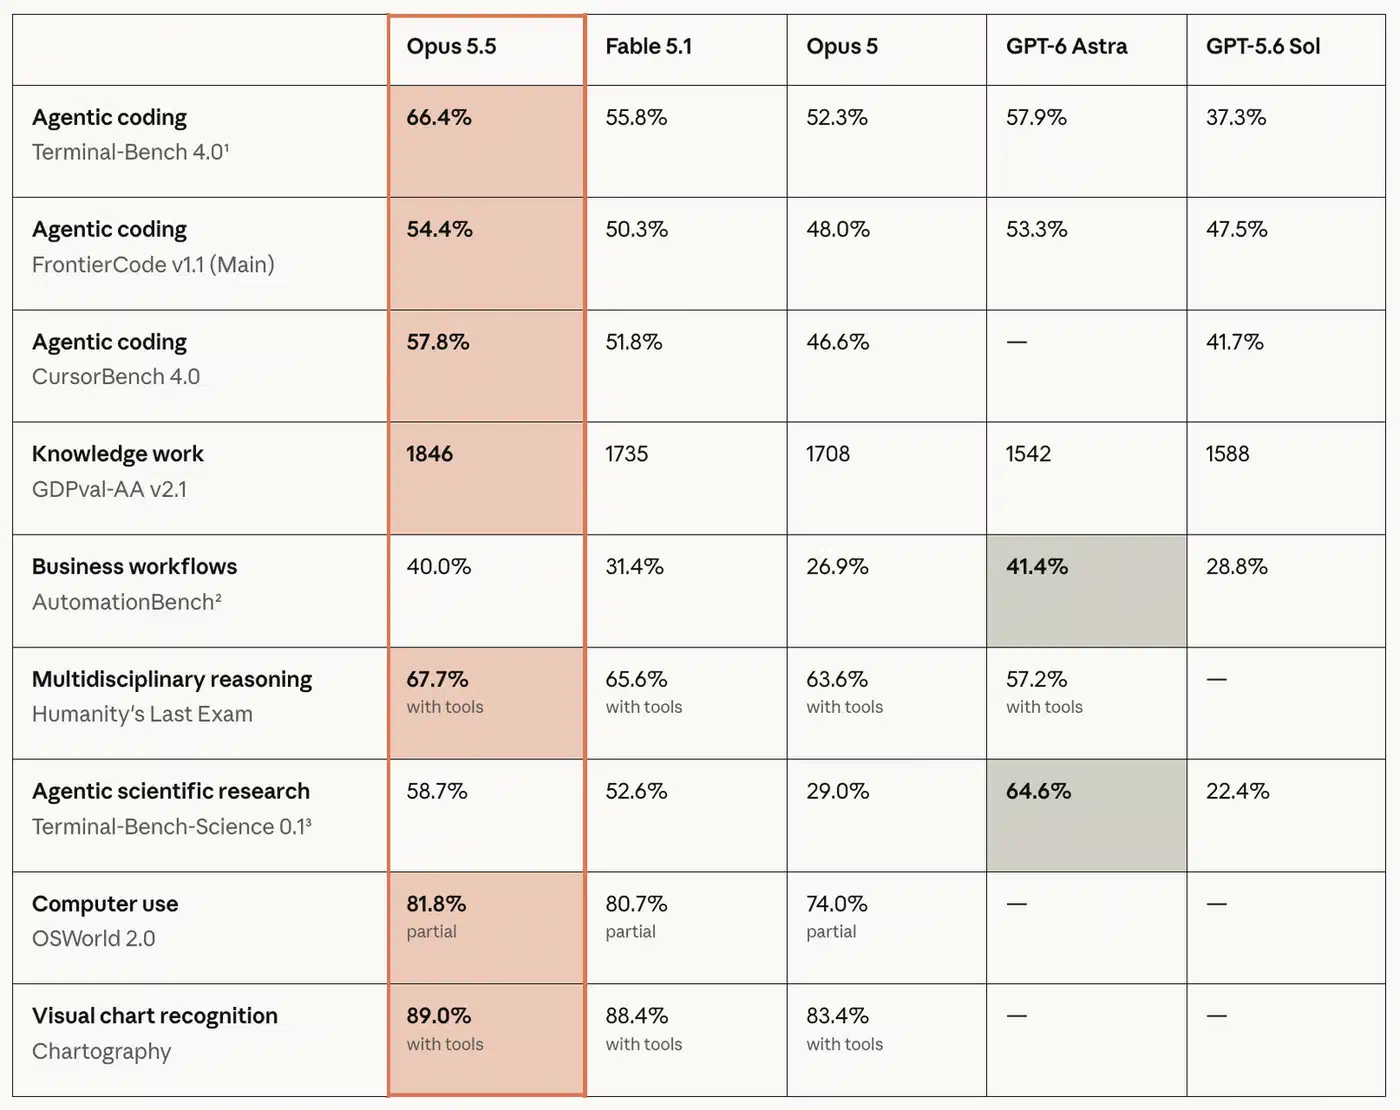
Reddit still discounts the chart. In r/singularity, one commenter says anyone who used Opus 5 knows not to trust these benchmarks. A well-upvoted r/ClaudeCode reply adds that mainstream benchmarks miss the real-world work people actually do.
Anthropic did run one same-task test against Fable 5.1. Both models translated HAProxy, the load balancer, from C to Rust, and both rewrites passed nearly all of HAProxy’s regression tests. Opus 5.5 finished in 9.5 hours against Fable’s 12, at 51% lower cost. That’s a vendor test on a well-defined port, while the Reddit loss above came on an open-ended feature in a real app.
One split fits both results: Opus 5.5 takes narrow, well-defined work. Fable 5.1 keeps large projects and planning, with Opus subagents doing the building, as one commenter suggests. The same “is Opus a Fable replacement” fight played out a generation earlier in Reddit’s Fable 5 vs Opus 4.8 verdict .
Reddit laughed at Anthropic’s pacing pledge
Opus 5.5 is Anthropic’s first release since it called for pacing the frontier. That call came in Dario Amodei’s essay We Must Pace the Frontier . Outside testers, including METR and Frontier Design , checked the model before release. The essay’s case rests on models that can fully automate AI research, which Anthropic holds to a higher safety bar. Opus 5.5 isn’t pitched as that kind of model.
Reddit skipped the nuance. The top comment in the biggest thread is three words long:
Pacing the frontier
A reply pointed out that nobody ever said how fast the pacing would be. In r/singularity, the read was competitive : so much for the slowdown, since Anthropic clearly hated watching Astra hold the crown for two weeks.
Reddit is already rewriting the Opus 5 story
A good release makes the last one look worse. On launch day, Anthropic researcher Nat McAleese posted this on X, the social network, and it passed 1 million views:
Opus 5.5 is way, way, way better than Opus 5. Sorry about that model, please try this one.
A screenshot of it drew 786 votes in the r/vibecoding forum on Reddit . The thread’s title reads it as proof that Anthropic knew Opus 5 was weak, which is the redditor’s reading, not the researcher’s words. The top comment joked about Opus 5 finding the post in its own training data next year. A sharper one accused Anthropic of holding Opus 5 back while it thought no rival was close, and predicted it would happen again.
Nobody outside Anthropic knows what went wrong. One theory holds that Opus 5 was a botched distillation of Mythos or Fable. Another says it should have shipped as a Sonnet. Either way, r/singularity’s mood was plain relief at dropping Opus 5 .
The nerf countdown and the complaints that are real
The most-upvoted skeptics say every launch looks like this before the model gets worse. The top one:
Queue the whining in two weeks about the model being nerfed.
A second commenter said Reddit is in the phase of the cycle where a new model can do no wrong. In r/OpenAI, one user expects the model to be quantized two weeks after the hype, and even the OpenAI loyalist who praised it expects a nerf within days. Others point out that Opus 5 was called amazing on day one too.
Biology safeguards now apply to Opus
Anthropic rates Opus 5.5 as close to Claude Mythos 5.1 in biology and cybersecurity, so it ships with the same biology safeguards as Fable 5.1. The docs list a biology safety classifier next to the cybersecurity one. Researchers who get blocked can apply to the new Life Sciences Verification Program . That’s cold comfort for a user working in sheep bioinformatics , who mocked the idea that the world needed protecting from their research.
Preserved thinking breaks edited conversations
One user says Opus 5.5 is broken for them, because thinking blocks become invalid after any change earlier in the context. A separate r/ClaudeAI report describes the same failure. The same docs page documents the behavior: the API checks whether the system prompt, tools or an earlier message changed since a thinking block was made. For accounts created on or after 2026-08-31, replaying such a block returns a 400 error.
The docs list two fixes. Keep the conversation append-only and change instructions through mid-conversation system messages. Alternatively, send the thinking-binding-controls-2026-08-01 beta header with prefix_mismatch_behavior set to "drop_block".